Hierarchical reinforcement learning for quadruped navigation
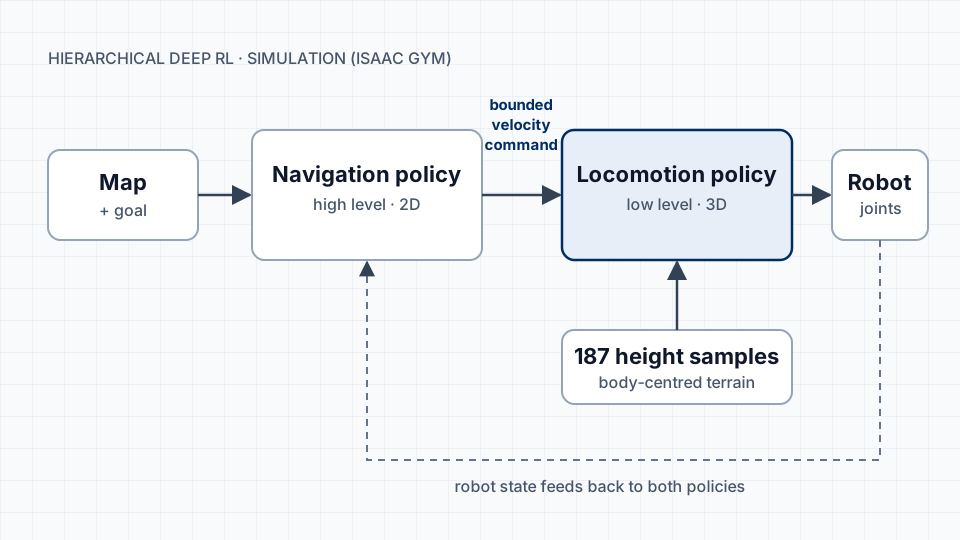
Two reinforcement-learning policies, one for navigation and one for locomotion, joined by a bounded velocity command. Simulation research presented at ICRoM 2025; thesis in progress.
Two reinforcement-learning policies, one for navigation and one for locomotion, joined by a bounded velocity command. Simulation research presented at ICRoM 2025; thesis in progress.