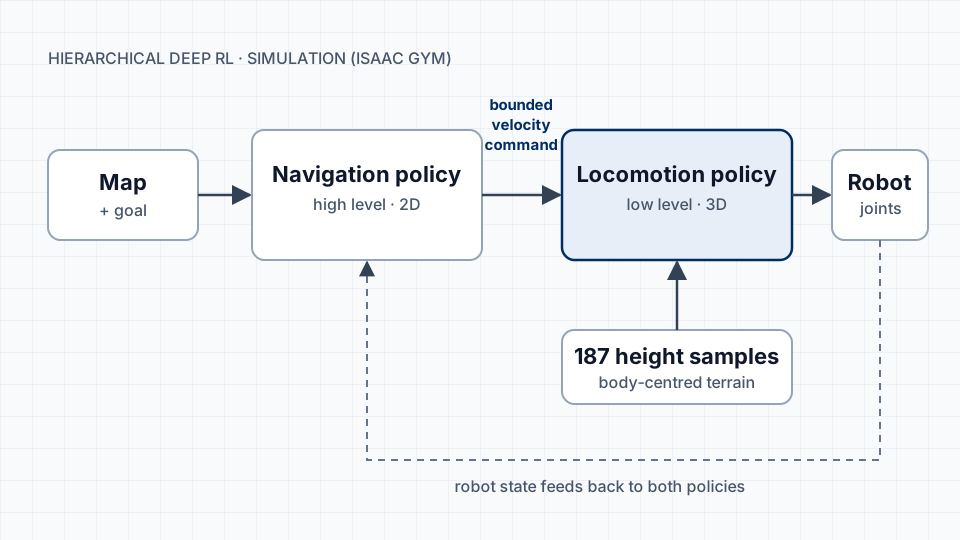
Hierarchical reinforcement learning for quadruped navigation
Two reinforcement-learning policies, one for navigation and one for locomotion, joined by a bounded velocity command. Simulation research presented at ICRoM 2025; thesis in progress.
Two reinforcement-learning policies, one for navigation and one for locomotion, joined by a bounded velocity command. Simulation research presented at ICRoM 2025; thesis in progress.
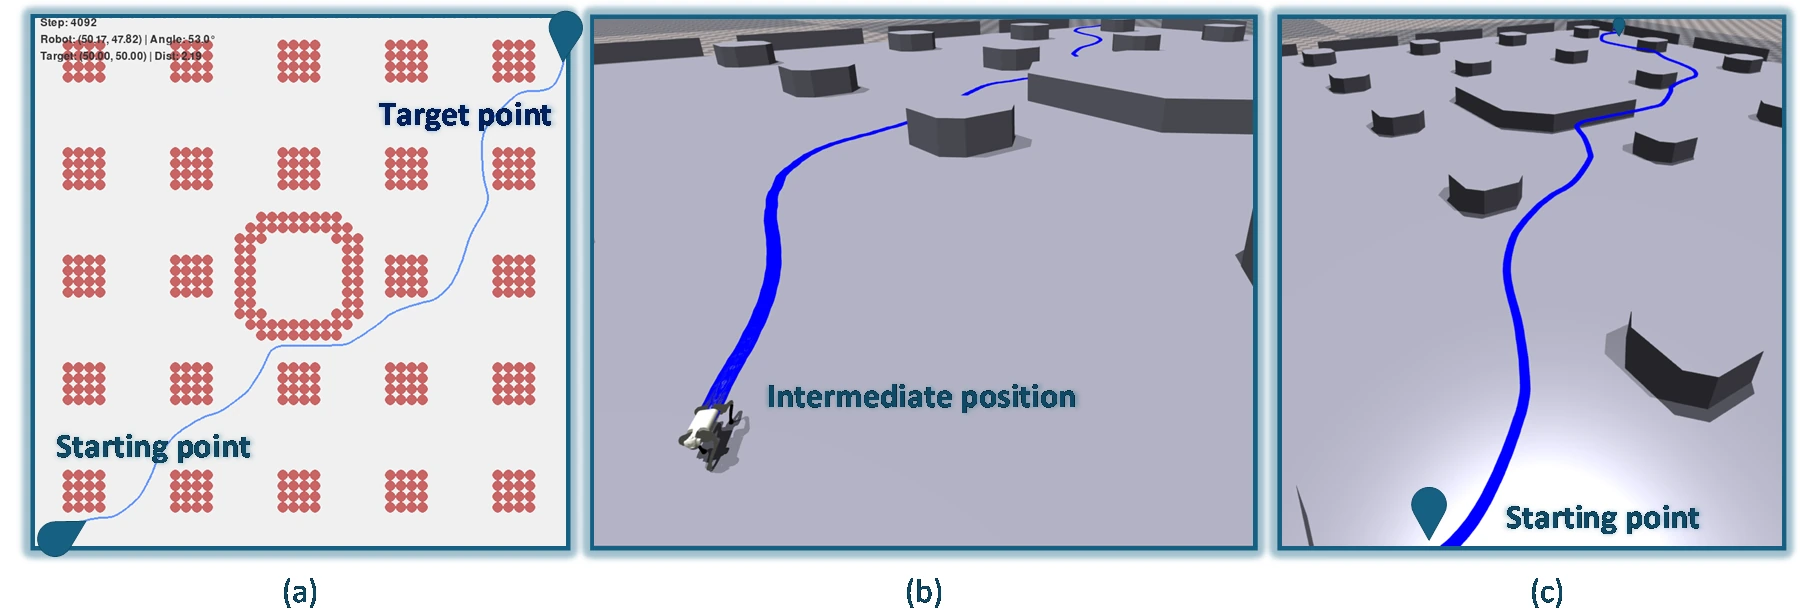
A two-policy framework for quadruped navigation over uneven terrain, evaluated in Isaac Gym. Read the research summary, explore the original figures and download the ICRoM 2025 paper.
This blog is a place for concise technical notes from my work in AI and robotics. The topics I plan to write about include ROS2 software architecture, reinforcement learning for control, Isaac Gym and Gazebo simulation workflows, multimodal robot data pipelines, and the practical details of connecting LLMs and VLMs to robotic systems. My goal is to keep the writing useful: implementation notes, design decisions, experiments, lessons from hardware integration, and research summaries that can help another engineer reproduce or improve the work.